Unified web genome editing platform for CRISPR–Cas variants, base editors, and prime editors
## Citing DeepGE Citing DeepGE in your publication sustains the maintenance and improvement of this web server and keeps the infrastructure available to everyone. > Available in the near future, please stay tuned. Moreover, please cite the specific paper(s) for the tool(s) you used. Citations are shown on each web server page. 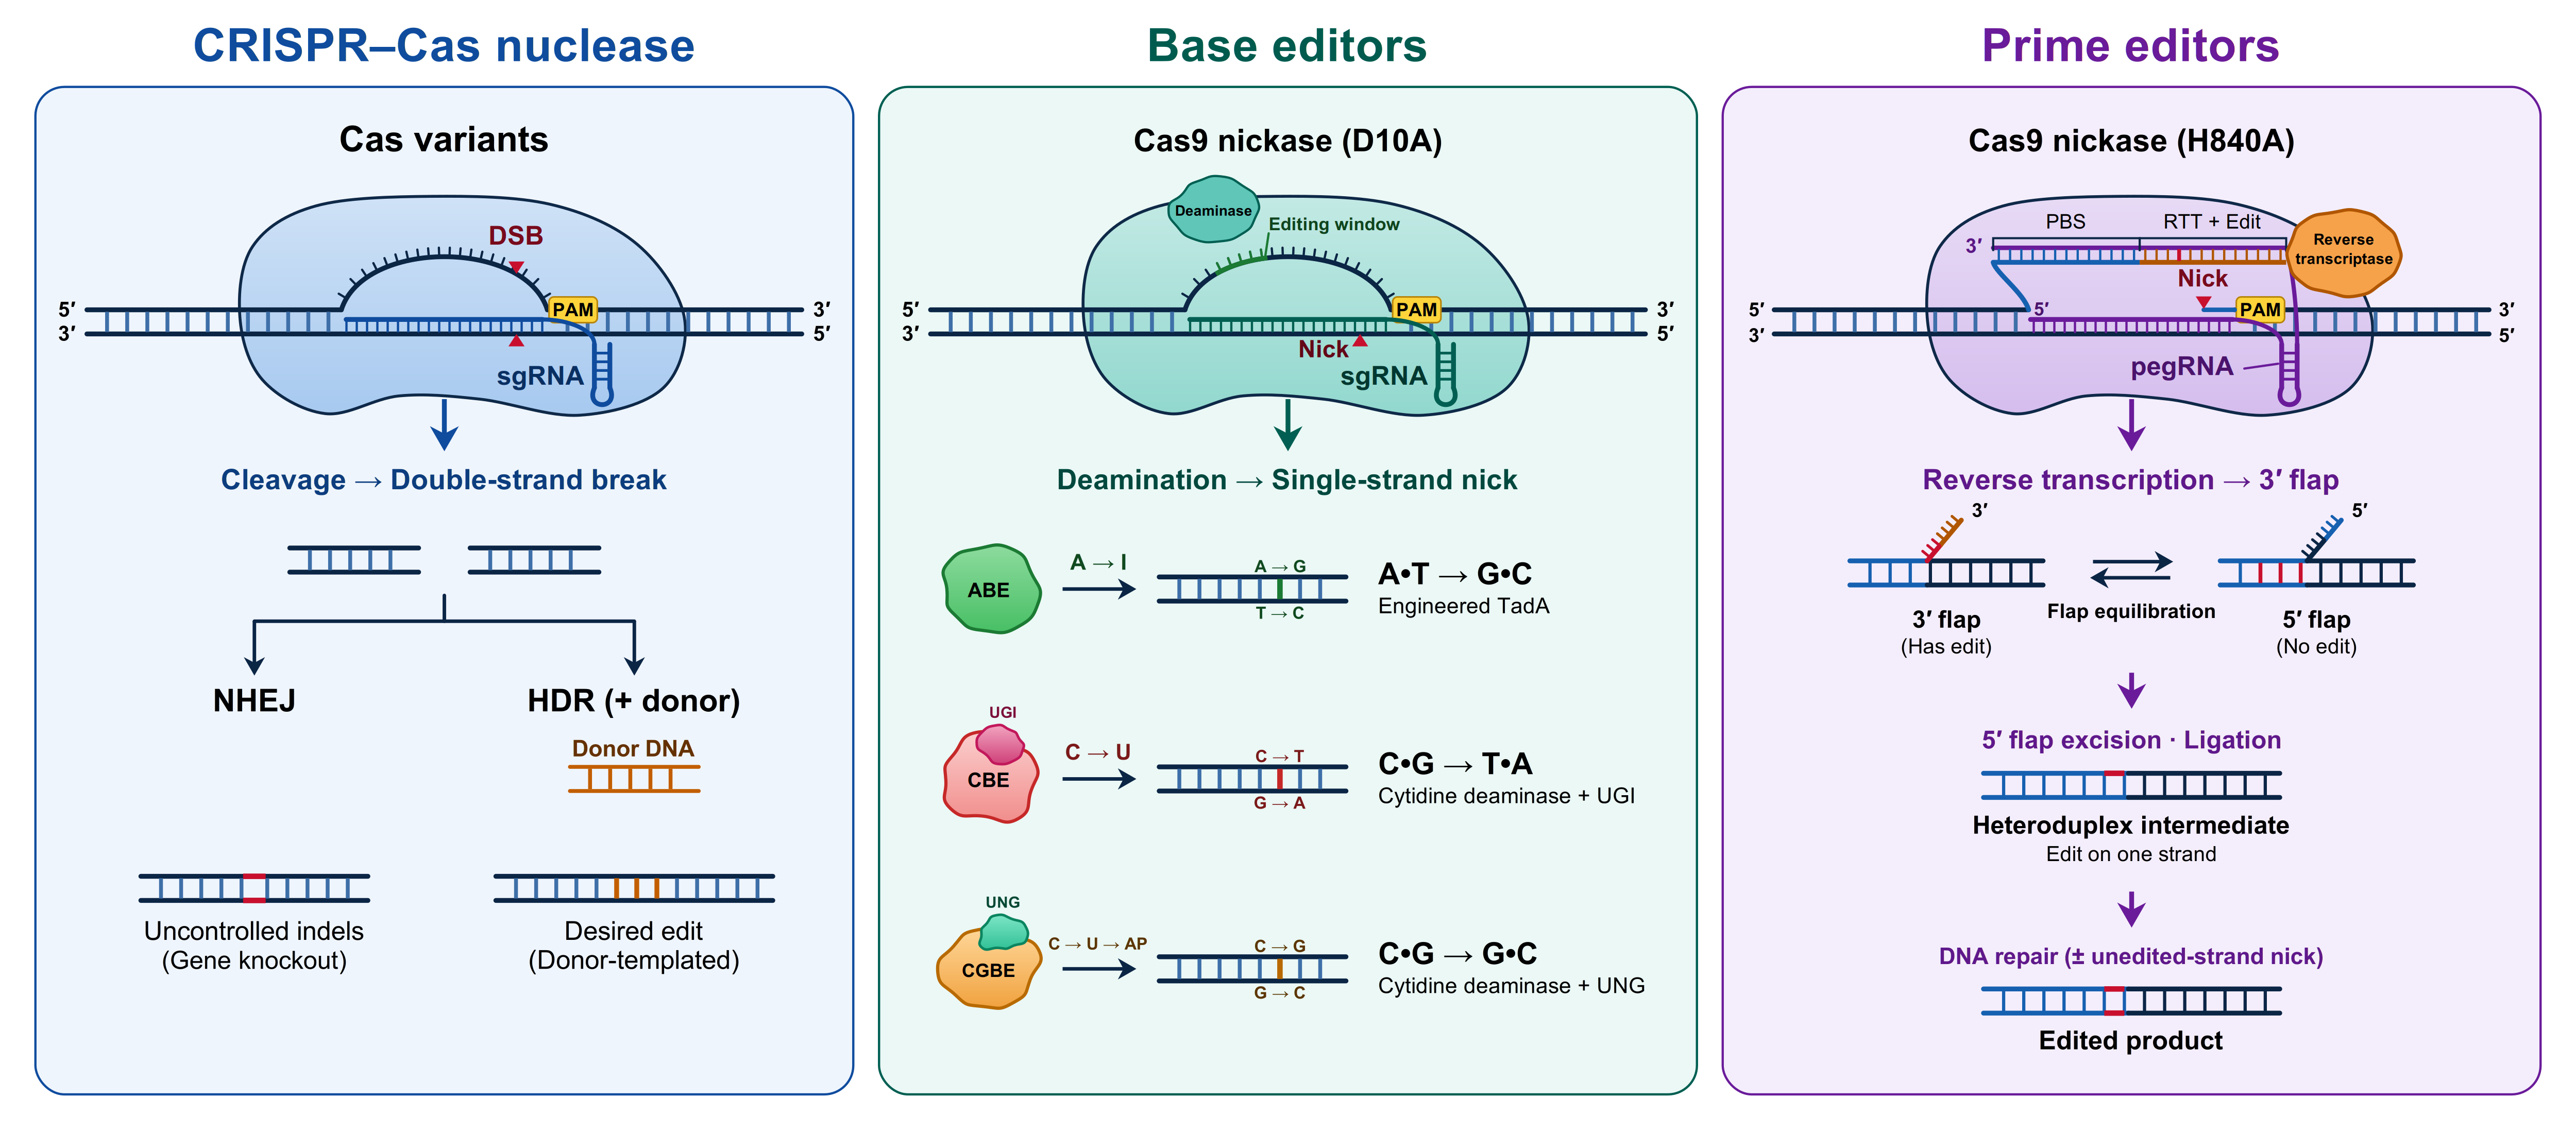 The three major modalities of genome editing are **CRISPR–Cas variants**, **Base editing**, and **Prime editing**. The documentation below provides a comprehensive guide to web servers and genome editing modalities. | Attribute | CRISPR–Cas variants | Base editors | Prime editors | |---|---|---|---| | **Core machinery** | RNA-guided Cas nuclease | Cas nickase fused to a deaminase | Cas nickase fused to a reverse transcriptase | | **Guide RNA** | Single guide RNA (sgRNA); a CRISPR RNA (crRNA) for Cas12a | sgRNA | pegRNA — spacer, primer binding site (PBS), and reverse transcription template (RTT); optional nicking sgRNA for PE3/PE5 | | **DNA break** | Double-strand break (DSB) | Single-strand nick — no DSB | Single-strand nick — no DSB; a second nick is introduced on the opposite strand for PE3/PE5 | | **Donor DNA** | Needed only for homology-directed repair (HDR) knock-in; not needed for non-homologous end joining (NHEJ) | Not needed | Not needed | | **What it can edit** | Knockouts, large deletions, and pooled screens (via NHEJ); precise insertion or replacement with a donor (via HDR) | Single-base conversions inside a small editing window | Substitutions, small insertions and deletions, and combinations thereof (covering all 12 base-to-base substitutions) | | **Single-base conversions covered** | Not a base-conversion tool | 6 of 12 as served — A→G / T→C (adenine base editors, ABE), C→T / G→A (cytosine base editors, CBE), C→G / G→C (C-to-G base editors, CGBE) | All 12 possible base-to-base conversions | | **Typical edit size** | NHEJ indels usually <20 bp; HDR ranges from 1 bp to several kb | One or more eligible bases within the window | ~1–60 bp with a single pegRNA; up to ~10 kb with paired pegRNAs | | **Typical efficiency** | NHEJ is often very high (~30–70%, sometimes >70%); HDR is generally low (~1–20%) and variable | High, and can be very high — for example ~60% precise editing in mouse liver, and 98–99% target modification by evolved adenine base editors in primary human T cells | Variable; can be substantial (e.g., ~46% in mouse liver) but is generally lower than that of base editors | | **Precision / unwanted edits** | Imprecise NHEJ indel spectrum; occasional large on-target deletions | Bystander edits when several eligible bases fall within the window | High precision with few byproducts | | **Off-target profile** | Guide-dependent; high-fidelity Cas variants available | Guide-dependent and guide-independent (DNA and RNA); high-fidelity deaminases available | Low — almost undetectable when more than three mismatches fall in the region corresponding to the primer-binding site | | **Size and adeno-associated virus (AAV) delivery** | Compact orthologs can fit in a single AAV; SpCas9 is difficult to package unless ultracompact promoters are used | Larger (extra deaminase) — single-AAV delivery is difficult | Largest (extra reverse transcriptase) — single-AAV delivery is difficult | | **Best suited for** | Gene disruption, large deletions, and pooled knockout screens; donor-templated knock-ins, at the lower efficiency of HDR | Gene disruption, installing or correcting disease-relevant point mutations (including in non-dividing cells), and pooled functional screens | Gene disruption, installing or correcting disease-relevant mutations (including in non-dividing cells), functional screens of selected genes, and larger insertions or deletions when using pairs of pegRNAs | | **Less suited for** | Precise edits without byproducts; precise editing (HDR) in non-dividing cells; applications sensitive to DSB-associated indels or large deletions | Targets with multiple editable bases (e.g., several Cs for CBE or As for ABE) within the editing window | Edits >~5 nt (which may be inefficient with a single pegRNA); efficiency is strongly dependent on the pegRNA sequence, and optimal design is often challenging | | **DeepGE coverage** | 37 CRISPR–Cas variants (SpCas9, SpCas9-NG and xCas9 are counted once per guide scaffold) | 65 base editors | 9 prime editors | Please refer to the descriptions below and [Kim, H.K., Kim, H.H. Evaluation and prediction of guide RNA activities in genome-editing tools. *Nature Reviews Bioengineering*, **4**, 82–97 (2026)](https://doi.org/10.1038/s44222-025-00352-z) for more information. ## What every design comes back with The pages below describe **which editor each web server predicts for**. This section describes what arrives in the results table whichever one you pick — the same derived columns, computed the same way, on every workflow that can support them. Every column here is also in the downloaded file, so what you read on the page is what you keep. | Output | Where it appears | What you get | |---|---|---| | **Cloning oligos** | 15 of 17 web servers — everywhere a guide is designed | A forward and reverse oligo pair, ready to order, with the overhangs of a named vector: SpCas9/lentiGuide-Puro (BbsI or BsmBI), Cas12a/pY108 or pU6-crRNA, Cas12a/pRDA_052 (Broad GPP), small-Cas9/Lenti-gRNA-Puro #84752, and a GG acceptor for pegRNA extensions. Every overhang stays editable, because an overhang belongs to your vector rather than to the nuclease. | | **HDR donor template** | The 9 CRISPR–Cas web servers, when the input carries an edit | A donor built around each guide's own cut site: **100 nt homology arms** by default (or 50 nt, or 25–1000 nt of your choosing), **sense, antisense or both strands**, as an **ssODN**, a **long single-stranded fragment** or a **double-stranded duplex**, with optional **silent PAM-blocking** mutations so the nuclease cannot re-cut the repaired allele. Donors for one target are ranked. | | **Off-target score** | Mismatch-tolerance on 9 web servers; whole-genome search on 11 | Two different questions, and the column headers say which. The **mismatch-tolerance** score needs no genome: it asks how much activity survives a single mismatch, scored on a published substitution table, and a **higher number is the worse guide**. The **genome-wide specificity** score comes from a real [Cas-OFFinder](https://doi.org/10.1093/bioinformatics/btu048) pass over GRCh38 or GRCm39 and runs the other way — **higher is better**. On 7 web servers you may aggregate that search with the **CFD** table, the **MIT/Hsu** position weights, or both side by side. DeepSniper and DeepSmallCas9 score searched sites with their nuclease's own published off-target model instead. | | **Position figure** | 13 web servers | Every candidate drawn where it sits in the sequence you submitted, above the table. Click a guide to filter the table to it; filter the table and the figure redraws to match. A results table states a position only as text like `59:132` — this is where that becomes a place. | | **Cut site and location** | Wherever a guide can be placed in your input | The cut position, 1-based in your own sequence, and the guide's span. For an input that names a locus — a gene, a variant, a coordinate — the genomic position is given as well. | | **epegRNA motifs** | The prime-editing web servers | A 3' structured motif appended to the pegRNA extension, from a chosen panel, with its own orderable oligo pair. It is never the default, because an epegRNA is a different construct to order and to publish than the pegRNA beside it. | Which of these a particular web server offers depends on what its model can support: a prime editor installs its own edit, so it is offered no HDR donor. ## CRISPR–Cas Variants CRISPR–Cas variants use an RNA-guided nuclease that binds a target defined by a **protospacer adjacent motif (PAM)** and introduces a **DSB**. The cell then repairs the break by **NHEJ** — efficient, template-free, and well suited to **knockouts**, **large deletions**, and **pooled screens**, though imprecise — or by **HDR**, which uses a donor template for **precise insertions** at lower efficiency. This modality is the right choice for disrupting genes or inserting sequences with a donor, but **not** for precise single-base changes without a template (use base or prime editors instead in this case). When a site lacks an efficient guide RNA or a usable PAM, switching to a different Cas variant — one with a different PAM or higher fidelity — is the usual solution. DeepGE covers **37 CRISPR–Cas variants**, spanning SpCas9, engineered high-fidelity and relaxed-PAM SpCas9 variants, including Sniper-Cas9, Cas12a (AsCas12a or AsCpf1), and compact orthologs. **Web servers:** | Web server | CRISPR–Cas variants / orthologs covered | Scaffold | gRNA architecture | Key predictions and features | Typical input | Key reference | |---|---|---|---|---|---|---| | **[DeepSpCas9variants](/workflows/DeepSpCas9variants)** | SpCas9 and 8 other variants: SpCas9-NG, VRQR variant, Sniper-Cas9, xCas9, eSpCas9(1.1), SpCas9-HF1, HypaCas9, evoCas9 | Optimized | (G/g)N19 and tRNA-N20 | **Default starting point**: Designs guide RNAs and predicts efficiency across 9 editors; fidelity ranking: evoCas9 ≫ HypaCas9 ≥ SpCas9-HF1 ≈ eSpCas9(1.1) > xCas9 > Sniper-Cas9 > SpCas9 | FASTA (≥30 bp), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID | [***Kim et al. Nature Biotechnology (2020)***](https://doi.org/10.1038/s41587-020-0537-9) | | **[DeepCas9variants](/workflows/DeepBE)** (via DeepBE) | SpCas9 and 8 other variants — SpCas9-NG, VRQR variant, SpCas9-NRRH, SpCas9-NRTH, SpCas9-NRCH, SpG, SpRY, Sc++ | Optimized | (G/g)N19 | Reached through **Comparison Mode** inside DeepBE; use when you need variants beyond DeepSpCas9variants | FASTA (≥30 bp), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID | [***Kim et al. Nature Biotechnology (2024)***](https://doi.org/10.1038/s41587-023-01792-x) | | **[DeepSmallCas9](/workflows/DeepSmallCas9)** | 17 compact orthologs/variants: sRGN3.1; SlugCas9 and SlugCas9-HF; SaCas9, SaCas9-KKH, SaCas9-HF, SaCas9-KKH-HF, eSaCas9, efSaCas9; SauriCas9 and SauriCas9-KKH; Sa-SlugCas9; St1Cas9; Nm1Cas9; Nm2Cas9; CjCas9 and enCjCas9 | Variant-specific | (G/g)N19-23 (variant-specific) | Designs guide RNAs and predicts efficiency for small nucleases; includes whole-genome off-target screening (bulge screening for sRGN3.1 and SlugCas9); recommended under strict size limits such as single-AAV packaging | FASTA (≥32–38 bp, depending on enzyme), gene symbol (human or mouse), NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID | [***Seo et al. Nature Methods (2023)***](https://doi.org/10.1038/s41592-023-01875-2) | | **[DeepCpf1](/workflows/DeepCpf1)** | CRISPR–Cas12a (AsCas12a / Cpf1 / AsCpf1) | N/A (Cas12a) | N/A (Cas12a) | Two models — **DeepCpf1** (uses chromatin accessibility / DNase-seq) and **Seq-DeepCpf1** (sequence only); the TTTV PAM of Cas12a enables editing in A/T-rich regions | FASTA (≥34 bp), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID | [***Kim et al. Nature Biotechnology (2018)***](https://doi.org/10.1038/nbt.4061) | | **[DeepSpCas9](/workflows/DeepSpCas9)** | SpCas9 | Conventional | (G/g)N19 | Efficiency prediction and guide design at endogenous sites | FASTA (≥30 bp), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID | [***Kim et al. Science Advances (2019)***](https://doi.org/10.1126/sciadv.aax9249) | | **[DeepSpCas9-NG](/workflows/DeepSpCas9-NG)** | [SpCas9-NG](https://doi.org/10.1126/science.aas9129) | Conventional | (G/g)N19 | Efficiency prediction and guide design for the relaxed-PAM SpCas9-NG | FASTA (≥30 bp), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID | [***Kim et al. Nature Biomedical Engineering (2020)***](https://doi.org/10.1038/s41551-019-0505-1) | | **[DeepxCas9](/workflows/DeepxCas9)** | [xCas9](https://doi.org/10.1038/nature26155) | Conventional | (G/g)N19 | Efficiency prediction and guide design for the broad-PAM xCas9 | FASTA (≥30 bp), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID | [***Kim et al. Nature Biomedical Engineering (2020)***](https://doi.org/10.1038/s41551-019-0505-1) | | **[DeepSniper](/workflows/DeepSniper)** | Sniper2L and Sniper1 (Sniper-Cas9) | Optimized | (G/g)N19 and tRNA-N20 | Predicts both on-target and off-target activity of high-fidelity Sniper variants across diverse PAMs | FASTA (≥30 bp), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID | [***Kim et al. Nature Chemical Biology (2023)***](https://doi.org/10.1038/s41589-023-01279-5) | | **[CINDEL](/workflows/CINDEL)** | CRISPR–Cas12a / Cpf1 (AsCpf1) | N/A (Cas12a) | N/A (Cas12a) | Logistic-regression model with Guide Finder, Single Sequence, and Batch Scoring modes (TTTV PAM); for deep-learning accuracy, prefer DeepCpf1 | Finder: FASTA (≥27 bp), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID. Batch: exactly 27 bp TTTV per line; Single: ≥27 bp, then pick a 27 bp TTTV candidate | [***Kim et al. Nature Methods (2017)***](https://doi.org/10.1038/nmeth.4104) | - **[DeepSpCas9variants](/workflows/DeepSpCas9variants)**: **Default starting point.** Designs guide RNAs and predicts efficiency for **SpCas9 and 8 other variants** (Sniper-Cas9, xCas9, eSpCas9(1.1), SpCas9-HF1, HypaCas9, evoCas9, VRQR variant, and SpCas9-NG) with an **optimized scaffold**. General fidelity ranking: evoCas9 ≫ HypaCas9 ≥ SpCas9-HF1 ≈ eSpCas9(1.1) > xCas9 > Sniper-Cas9 > SpCas9. - **[DeepCas9variants](/workflows/DeepBE)**: Select **`DeepCas9variants`** in the **Comparison Mode** of **[DeepBE](/workflows/DeepBE)** for **6 additional Cas9 variants** (SpCas9-NRRH, SpCas9-NRTH, SpCas9-NRCH, SpG, SpRY, Sc++, in addition to SpCas9, VRQR variant, and SpCas9-NG) with an optimized scaffold, when you need variants beyond those in DeepSpCas9variants. - **[DeepSmallCas9](/workflows/DeepSmallCas9)**: Designs guide RNAs for **17 small Cas9 orthologs and variants** (sRGN3.1; SlugCas9 and SlugCas9-HF; SaCas9, SaCas9-KKH, SaCas9-HF, SaCas9-KKH-HF, eSaCas9, efSaCas9; SauriCas9 and SauriCas9-KKH; Sa-SlugCas9; St1Cas9; Nm1Cas9; Nm2Cas9; CjCas9 and enCjCas9). Recommended under **strict size limits** (e.g., single-AAV packaging) and includes whole-genome **off-target screening** (bulge screening for sRGN3.1 and SlugCas9). - **[DeepCpf1](/workflows/DeepCpf1)**: Designs guide RNAs for **CRISPR–Cas12a (Cpf1)**, which uses a **TTTV PAM** and enables editing in **A/T-rich regions**. Predicts activity with chromatin accessibility (DeepCpf1) or from sequence alone (Seq-DeepCpf1). - **[DeepSpCas9](/workflows/DeepSpCas9)**, **[DeepSpCas9-NG](/workflows/DeepSpCas9-NG)**, and **[DeepxCas9](/workflows/DeepxCas9)**: Efficiency predictions for **SpCas9**, **SpCas9-NG**, and **xCas9** respectively, using the **conventional scaffold**. - **[DeepSniper](/workflows/DeepSniper)**: Designs guide RNAs and predicts **on- and off-target** activity for the high-fidelity **Sniper2L and Sniper1 (Sniper-Cas9)** variants across diverse PAMs. - **[CINDEL](/workflows/CINDEL)**: A machine-learning model for **Cas12a/Cpf1 (AsCas12a/AsCpf1)** activity; for deep-learning predictions, prefer **[DeepCpf1](/workflows/DeepCpf1)**. ## Base Editors Base editors fuse a **deaminase** to a **Cas nickase**, chemically rewriting a single base within a small **editing window** using only a **single-strand nick** — no double-strand break and no donor DNA. They are **efficient** (about **60%** precise editing in mouse liver, and **98–99%** target modification by evolved adenine base editors in primary human T cells) and, as served here, perform **6 of the 12** possible single-base conversions: **A → G / T → C** (ABE), **C → T / G → A** (CBE), and **C → G / G → C** (CGBE). The main caveats are **bystander edits** within the window (the deaminase may edit every eligible base, not just the intended one), sequence-context and PAM constraints, and a **larger payload** from the deaminase that complicates single-AAV delivery. Base editors are ideal for installing or correcting **point mutations** and for gene disruption via stop-codon or splice-site edits. DeepGE covers a total of **65 base editors**. **Web servers:** | Web server | Base editors covered | Key predictions and features | Typical input | Key reference | |---|---|---|---|---| | **[DeepBE](/workflows/DeepBE)** | 7 deaminase modules — ABE8e(V106W), ABE8.17m+V106W, YE1-BE4max, SsAPOBEC3B, CGBE1, miniCGBE1, APOBEC-nCas9-Ung — each paired with 9 Cas9 variants (SpCas9, SpCas9-NG, VRQR, SpCas9-NRRH, SpCas9-NRTH, SpCas9-NRCH, SpG, SpRY, Sc++), spanning ABE, CBE, and CGBE | **Default and most comprehensive**: Predicts efficiency and outcome proportions; offers single-editor and comparison modes; also hosts the DeepCas9variants models | Comparison mode: FASTA (≥30 bp; edit direction selected), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID. Single-editor mode: one target sequence (≥30 bp), then pick a 30 bp candidate | [***Kim et al. Nature Biotechnology (2024)***](https://doi.org/10.1038/s41587-023-01792-x) | | **[DeepBaseEditor](/workflows/DeepBaseEditor)** | ABE7.10 (ABE) and BE4 (CBE) | Designs optimized guide RNAs and predicts efficiency plus outcome proportions for the two classic editors | FASTA (≥25 bp for CBE, ≥26 bp for ABE), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID | [***Song et al. Nature Biotechnology (2020)***](https://doi.org/10.1038/s41587-020-0573-5) and [***Park and Kim Methods in Molecular Biology (2023)***](https://doi.org/10.1007/978-1-0716-2879-9_3) | | **[BEvariants](/workflows/BEvariants)** | ABE / CBE sgRNA library screen (not an efficiency predictor) | Reports the functional effects of cancer-related transition mutations on lung-cell survival and proliferation, searchable by gene name; for efficiency on arbitrary sequences, use DeepBE | Gene-name lookup | [***Kim et al. Nature Biotechnology (2022)***](https://doi.org/10.1038/s41587-022-01276-4) | - **[DeepBE](/workflows/DeepBE)**: **Default and most comprehensive.** Designs guide RNAs and predicts the efficiencies and outcomes of a broad set of base editors (either ABE8e(V106W), ABE8.17m+V106W, YE1-BE4max, SsAPOBEC3B, CGBE1, miniCGBE1, or APOBEC-nCas9-Ung, each fused to either SpCas9, SpCas9-NG, VRQR variant, SpCas9-NRRH, SpCas9-NRTH, SpCas9-NRCH, SpG, SpRY, or Sc++) across **ABE, CBE, and CGBE**, providing both single-editor and comparison modes (DeepBE also hosts the **DeepCas9variants** models, noted above). - **[DeepBaseEditor](/workflows/DeepBaseEditor)**: Designs optimized guide RNAs and predicts efficiencies and outcomes for **ABE7.10 (ABE)** and **BE4 (CBE)**. - **[BEvariants](/workflows/BEvariants)**: Reports the **functional effects of cancer-related transition mutations** evaluated with ABE/CBE sgRNA libraries, searchable by **gene name**. For efficiency prediction on arbitrary sequences, use **[DeepBE](/workflows/DeepBE)** instead. ## Prime Editors Prime editors pair a **Cas9 nickase** with a **reverse transcriptase**, guided by a **prime editing guide RNA (pegRNA)** that both specifies the target and templates the edit. Prime editing is the most versatile modality: it installs **all 12 single-base substitutions** and **small insertions and deletions** without a double-strand break or donor DNA. The trade-offs are **lower efficiency** than base editors, more complex design (a spacer plus tuned **PBS** and **RTT** lengths), and a **larger construct** owing to the reverse transcriptase. Prime editing is the most convenient choice for arbitrary precise edits and for **saturation genome editing (SGE)**. DeepGE covers **9 prime editors**. **Web servers:** | Web server | Prime editor systems / models | Key predictions and features | Typical input | Key reference | |---|---|---|---|---| | **[DeepPrime](/workflows/DeepPrime)** | Diverse prime editing (PE) systems across multiple cell types | **Default for single-target design**: Evaluates and ranks all possible pegRNAs for one target by the DeepPrime score | Unedited/edited sequence pair (121 bp offers the fullest set of candidates; a shorter pair is designed from and offers fewer), ClinVar ID, or COSMIC ID | [***Yu et al. Cell (2023)***](https://doi.org/10.1016/j.cell.2023.03.034) | | **[SynDesign](/workflows/SynDesign)** | Built on DeepPrime / DeepPrime-FT | **Default for multi-target design and SGE**: Automated pegRNA design, evaluation, and library construction with extensive saturation genome editing support | FASTA (≥121 bp recommended), unedited/edited sequence pair (121 bp recommended), gene symbol, RefSeq NM, Ensembl, HGNC, ClinVar, COSMIC, or genomic position | [***Park et al. Nucleic Acids Research (2024)***](https://doi.org/10.1093/nar/gkae304) | | **[DeepPE](/workflows/DeepPE)** | PE2 (DeepPE + PE\_type + PE\_position models) | Predicts PE2 efficiency for 57 pegRNA designs per target (24 + 23 + 10) | FASTA (≥47 bp), gene symbol, NMID, Ensembl ID, HGNC ID, genomic position, unedited/edited sequence pair, ClinVar ID, or COSMIC ID | [***Kim et al. Nature Biotechnology (2021)***](https://doi.org/10.1038/s41587-020-0677-y) | | **[PEselector](/workflows/PEselector)** | hyPE2 | Scores hyPE2 prime editors and returns regression and classification scores plus a DeepSpCas9 score | Target / RTT / PBS sequence triplets | [***Song et al. Nature Communications (2021)***](https://doi.org/10.1038/s41467-021-25928-2) | | **[EGFRvariants](/workflows/EGFRvariants)** | EGFR tyrosine kinase domain variants, exons 18–24 (a published screen, not an efficiency predictor) | Reports how each EGFR variant responds to afatinib, dacomitinib or osimertinib on an activating **EGFR L858R** or **exon 19 deletion** background, with the variants installed by prime editing; for efficiency on arbitrary targets use DeepPrime or SynDesign | Dataset, activating context and tyrosine kinase inhibitor selection | [***Kim et al. Nature Biotechnology (2025)***](https://doi.org/10.1038/s41587-024-02465-z) and [***Lee et al. npj Precision Oncology (2026)***](https://doi.org/10.1038/s41698-026-01726-1) | - **[DeepPrime](/workflows/DeepPrime)**: **Default starting point for single-target design.** Evaluates **all possible pegRNAs** for a single unedited and edited sequence pair or a single ClinVar variant, and ranks them by predicted efficiency across **diverse prime editor systems and cell types**. For best results, provide a **121 bp** sequence (a 60 bp flank on each side of the target site). - **[SynDesign](/workflows/SynDesign)**: **Default starting point for multi-target design.** Automated **pegRNA design, evaluation, and library construction**, built on **DeepPrime/DeepPrime-FT**. Accepts FASTA sequences (requires 60 bp flanks on each side for full coverage), gene symbols, RefSeq/Ensembl/HGNC IDs, ClinVar/COSMIC IDs, or genomic coordinates, with extensive **SGE** support. - **[DeepPE](/workflows/DeepPE)**: Predicts **PE2** efficiencies for **57 pegRNA designs** per target (combining the DeepPE, PE\_type, and PE\_position models). - **[PEselector](/workflows/PEselector)**: Selects and scores **hyPE2** prime editors from **Target / RTT / PBS** sequence triplets using a machine-learning model. - **[EGFRvariants](/workflows/EGFRvariants)**: A **published prime-editing screen** rather than a design tool. Reports the measured drug response of each **EGFR tyrosine kinase domain** variant to a tyrosine kinase inhibitor; use **DeepPrime** or **SynDesign** to design pegRNAs. ## Contact If you have any questions, bug reports, or suggestions, please do not hesitate to contact us through the [Support](/support) page.